What Do We Do When the Agent Doesn't Learn? RL Debugging Explained from Scratch
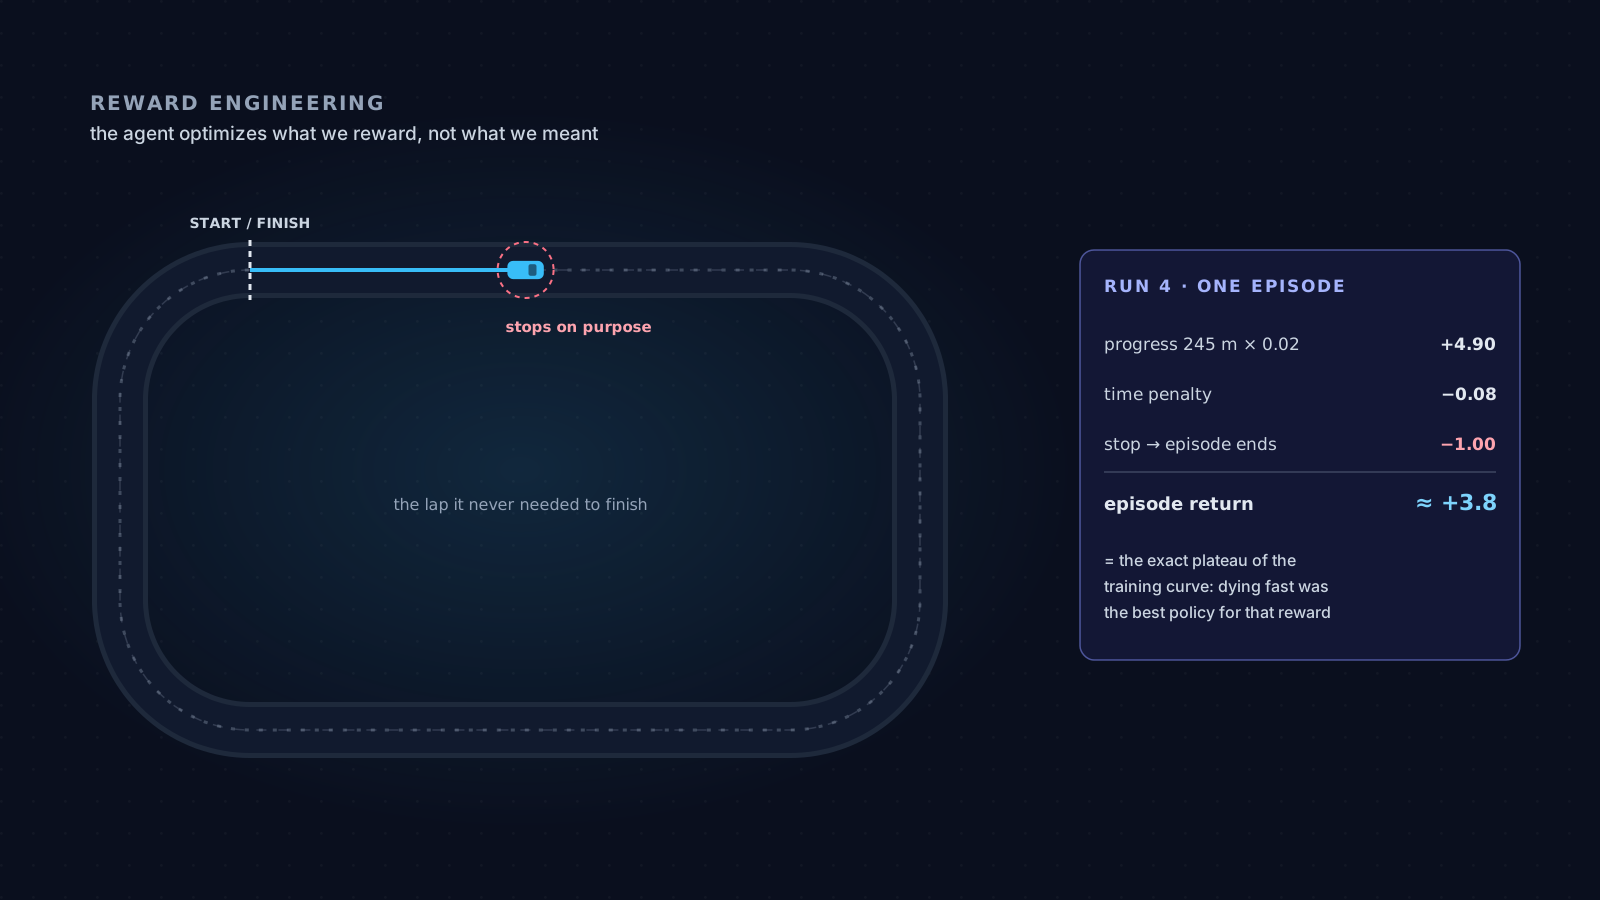
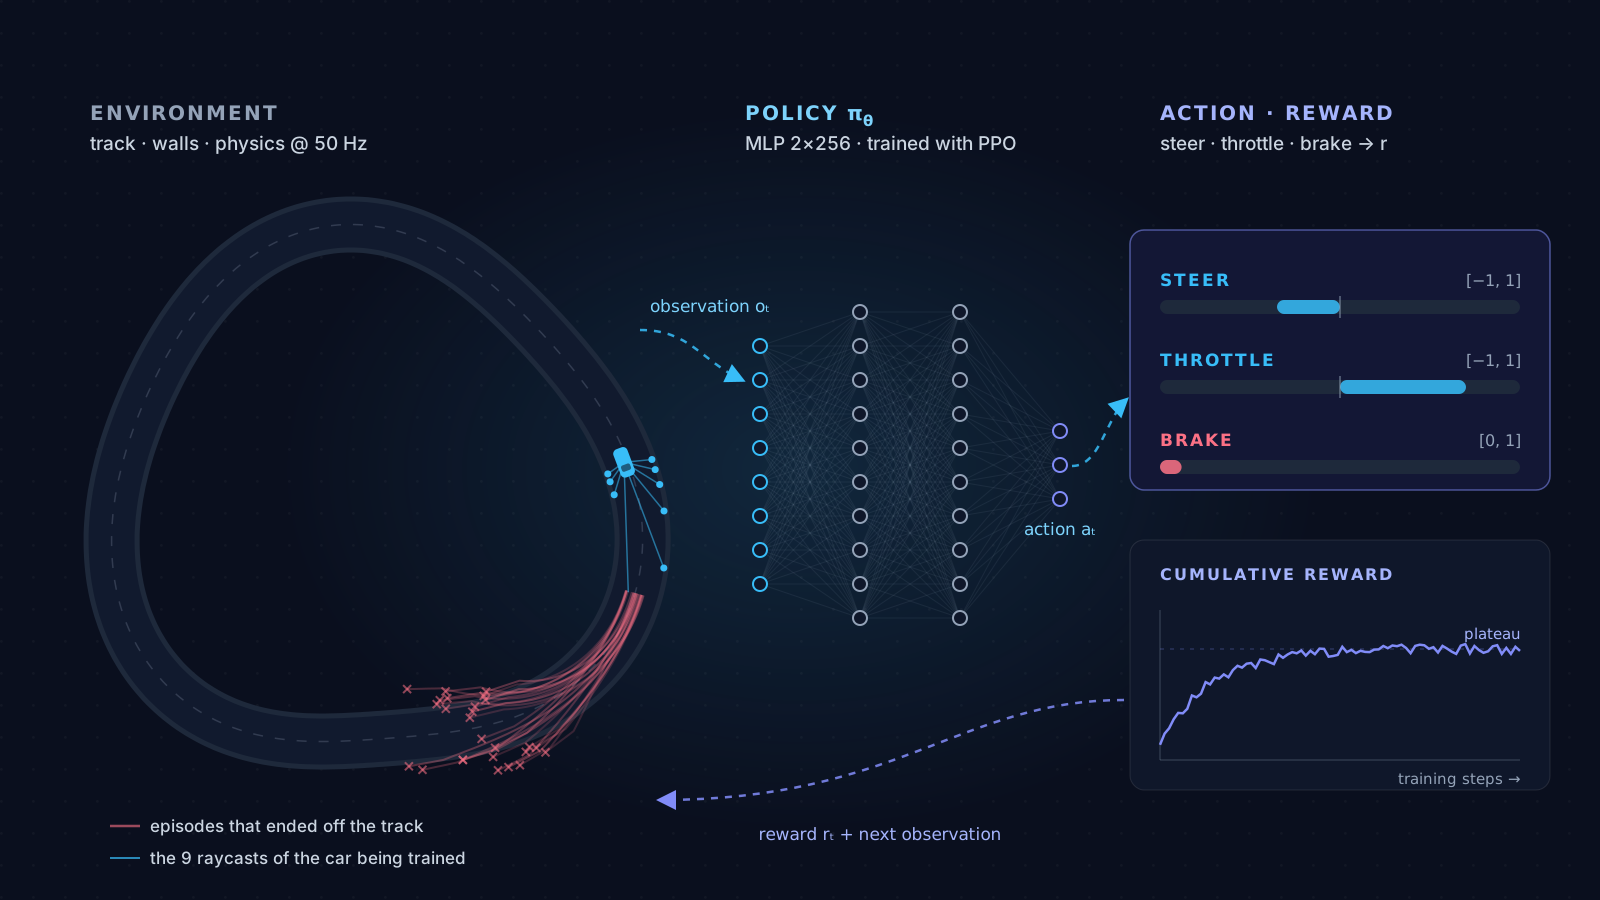
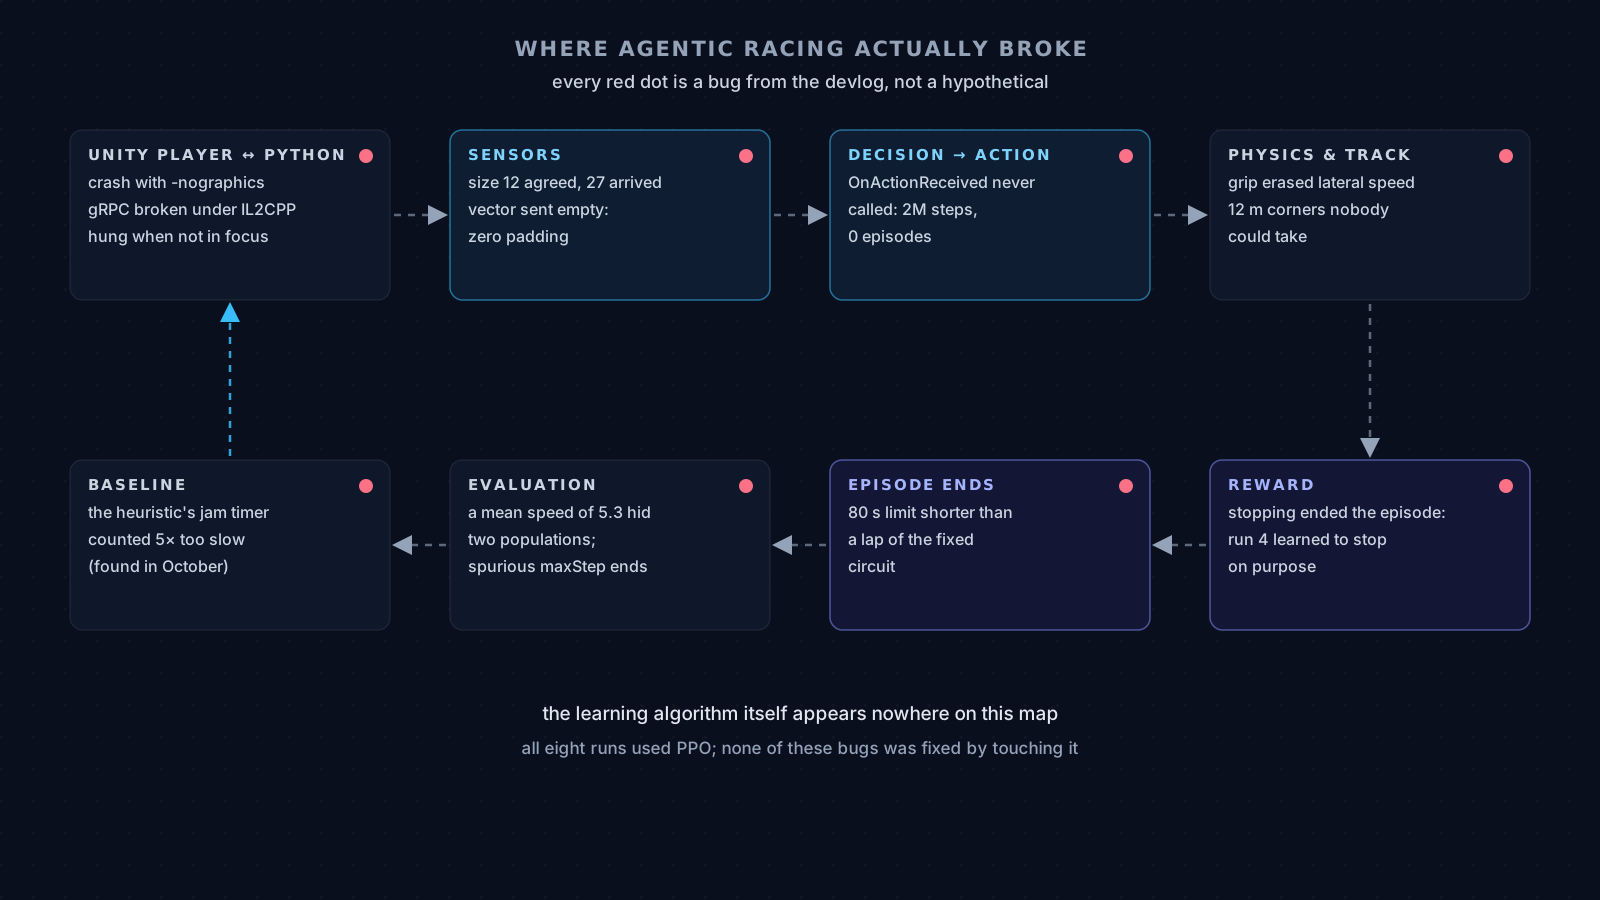
Part 8 of the Reinforcement Learning from scratch series with Agentic Racing. How to turn "the agent doesn't learn" into testable hypotheses, told through the real debugging of the project's RL pilot: at least six plumbing bugs before the first run, eight PPO runs with the lap fraction stuck, a baseline that had a bug of its own, misleading averages, termination versus truncation in ML-Agents, and the process mistakes that cost the most time.